Ongoing
Mechanistic Interpretability of LLMs
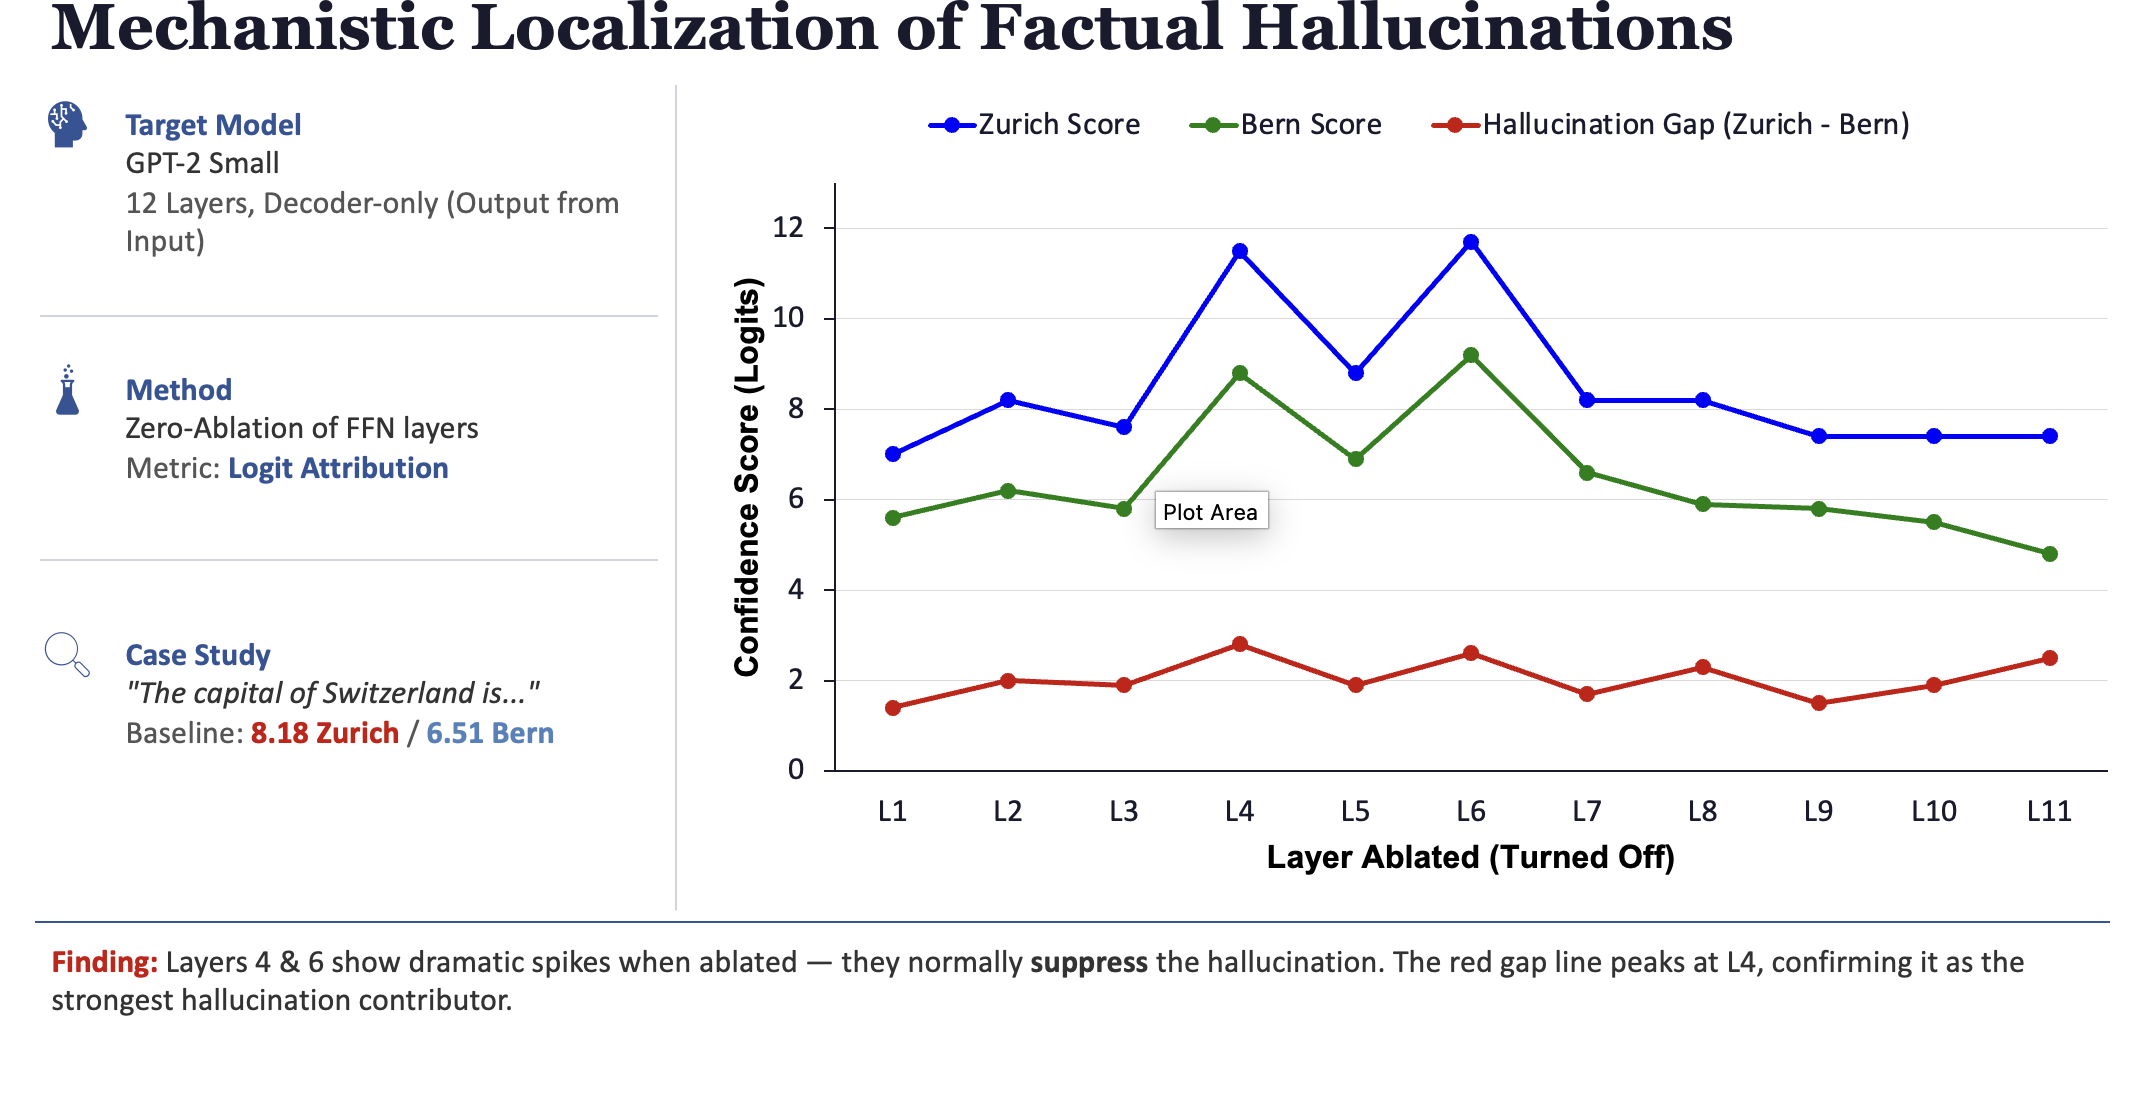
Ongoing work with Dr. Vivya Kalidindi on how GPT-2 represents and processes information across its layers, using layer-wise ablation and logit attribution to trace factual recall, hallucinations, and model confidence.
moreless
- Research question
- Which layers of a transformer carry a fact to the output, and which ones suppress it, when a model recalls, hallucinates, or hedges?
- My contribution
- Layer-wise zero-ablation of GPT-2's feed-forward layers to measure each layer's effect on predictions, and logit attribution across the residual stream with TransformerLens and PyTorch.
- Findings
- Preliminary: a small set of candidate "source" layers that raise the right answer and "inhibitor" layers that hold it back, which together may help localize factual knowledge and latent hallucinations.